Each model says what it is for.
What each one does, how much context it holds and what it costs. Then how our training programme works, and where it stands today.
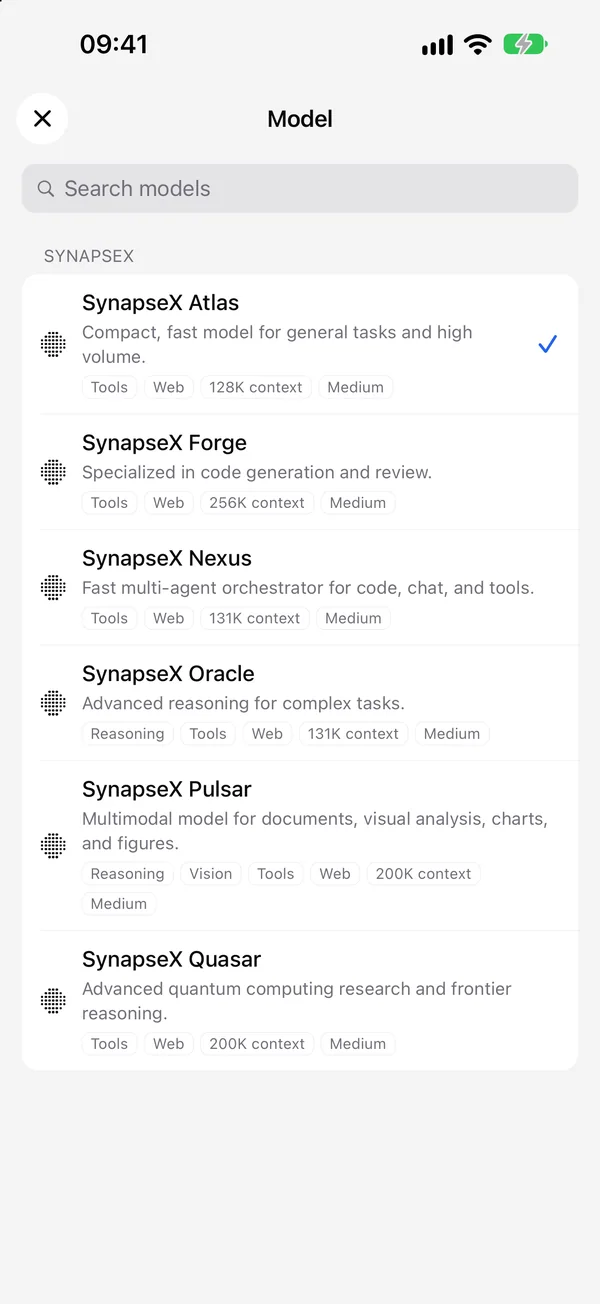
The models in SynapseX Chat.
SynapseX Atlas
Compact, fast model for general tasks and high volume.
Try in Chat- Context
- 128K
- Input per 1M tokens
- US$0.13
- Output per 1M tokens
- US$0.65
- Tools
- Web search
Use it for
General tasks, High volume
SynapseX Forge
Specialized in code generation and review.
Try in Chat- Context
- 256K
- Input per 1M tokens
- US$0.40
- Output per 1M tokens
- US$1.20
- Tools
- Web search
Use it for
Code generation, Code review
SynapseX Nexus
Fast multi-agent orchestrator for code, chat, and tools.
Try in Chat- Context
- 131K
- Input per 1M tokens
- US$0.25
- Output per 1M tokens
- US$0.67
- Tools
- Web search
Use it for
Multi-agent orchestration, Code, chat and tools
SynapseX Oracle
Advanced reasoning for complex tasks.
Try in Chat- Context
- 131K
- Input per 1M tokens
- US$2.27
- Output per 1M tokens
- US$4.53
- Tools
- Web search
- Reasoning
Use it for
Complex reasoning
SynapseX Pulsar
Multimodal model for documents, visual analysis, charts, and figures.
Try in Chat- Context
- 200K
- Input per 1M tokens
- US$3.50
- Output per 1M tokens
- US$14.00
- Tools
- Web search
- Vision
- Reasoning
Use it for
Documents, Visual analysis, Charts and figures
SynapseX Quasar
Advanced quantum computing research and frontier reasoning.
Try in Chat- Context
- 200K
- Input per 1M tokens
- US$3.50
- Output per 1M tokens
- US$14.00
- Tools
- Web search
Use it for
Quantum computing research, Frontier reasoning
Read from the live SynapseX Chat model list. A price the site could not read shows as unknown, never as a guess.
Which one for which work.
Atlas is the compact one: general tasks, in high volume, in the language you write.
Forge generates and reviews code. Nexus orchestrates several agents across code, chat and tools.
Pulsar reads documents, charts and figures, and works with what it sees.
Oracle is for complex reasoning. Quasar is for quantum computing research and frontier reasoning.
What the answers look like.
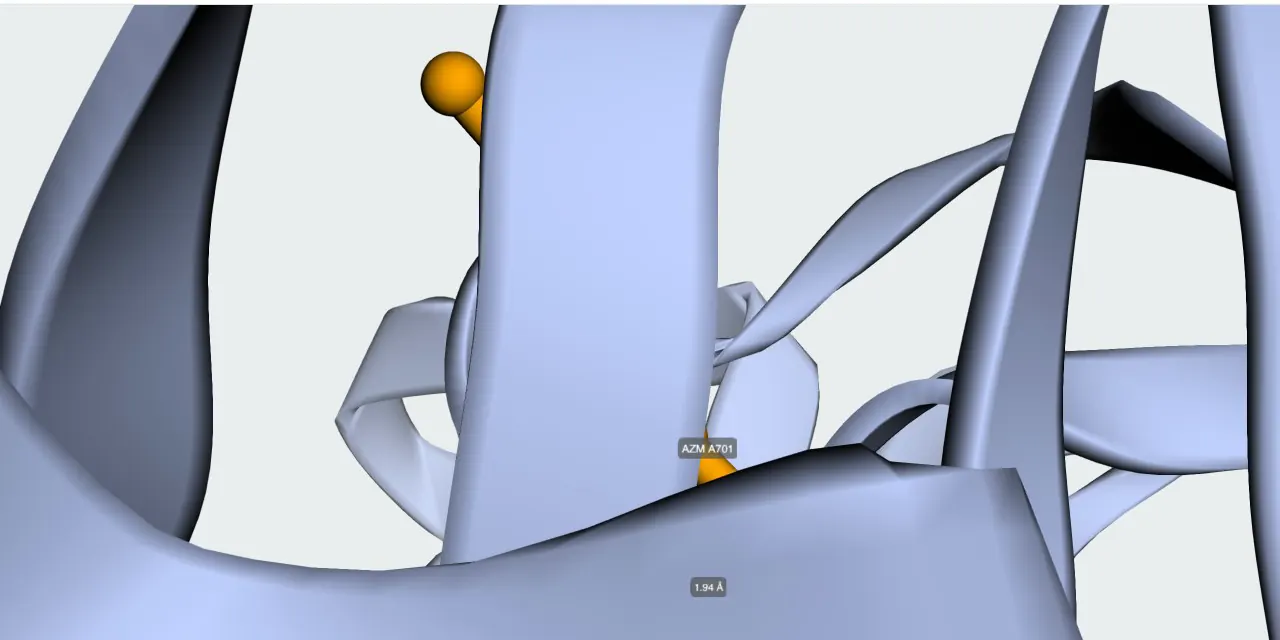
Turn a protein in 3D
Human carbonic anhydrase II with acetazolamide, PDB 3HS4, in the structure viewer.
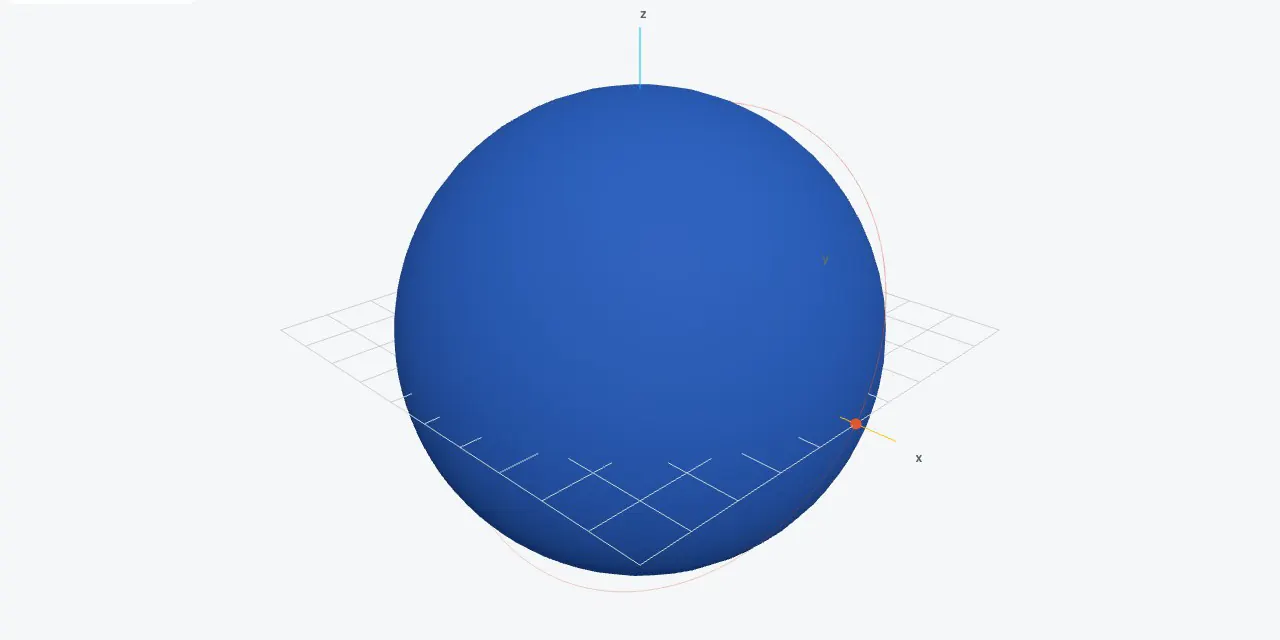
Follow an orbit
A 420 km orbit at 51.6 degrees in the trajectory viewer, computed from the closed form.
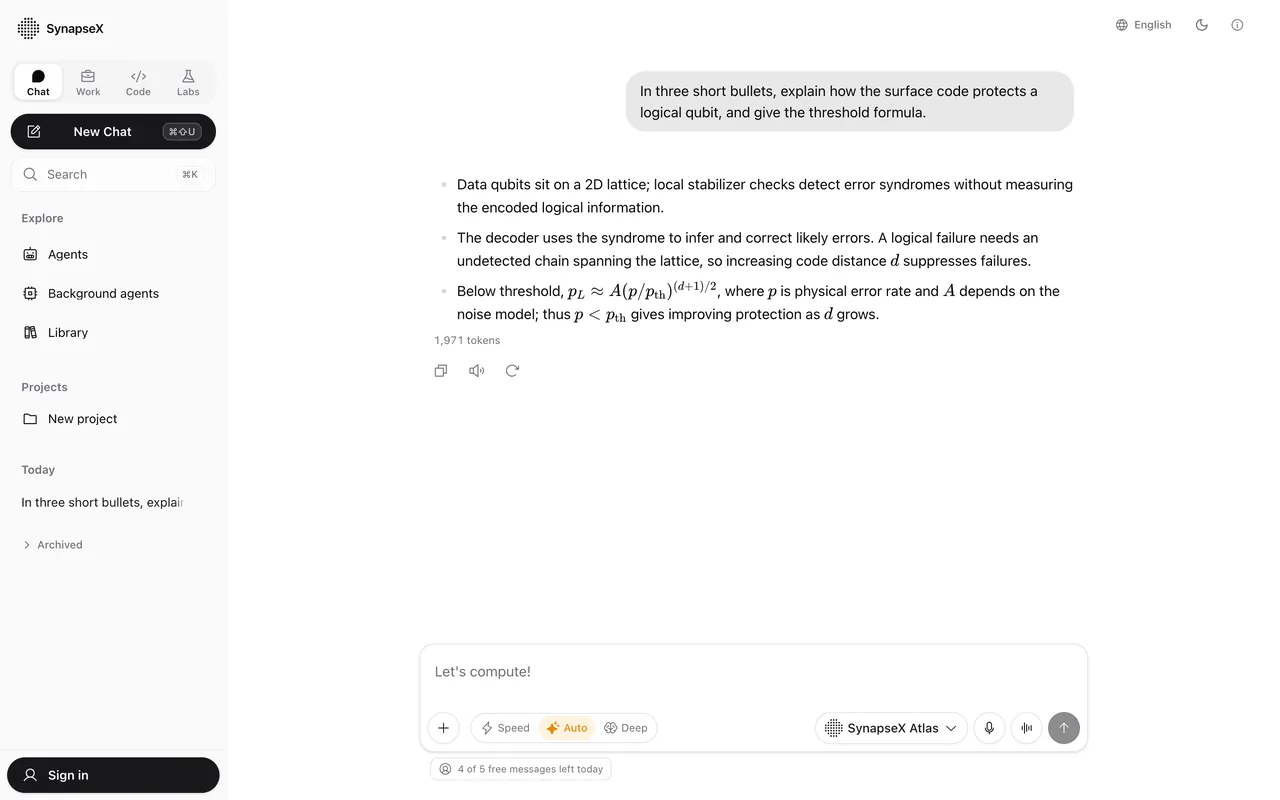
Ask how error correction works
An answer on how the surface code protects a logical qubit, with its threshold formula.
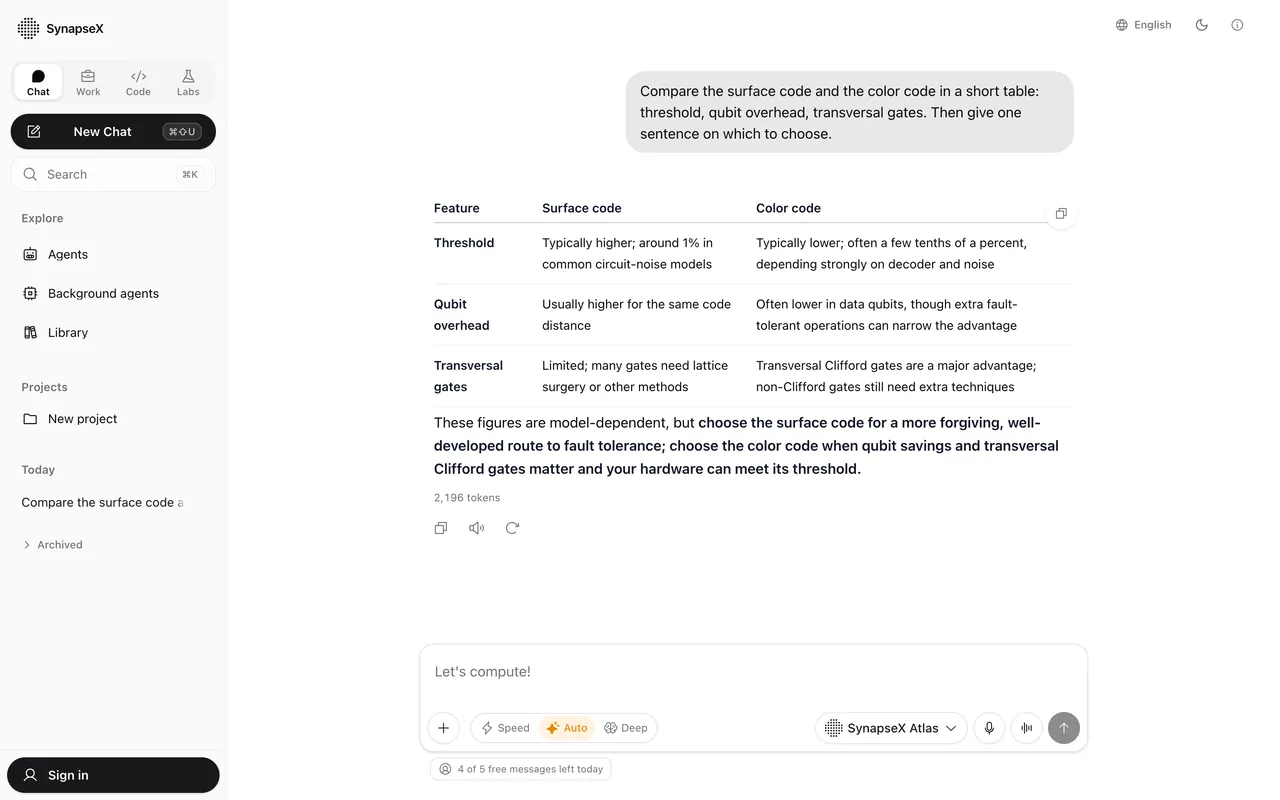
Compare two codes
Surface code and color code side by side, with a sentence on which to choose.
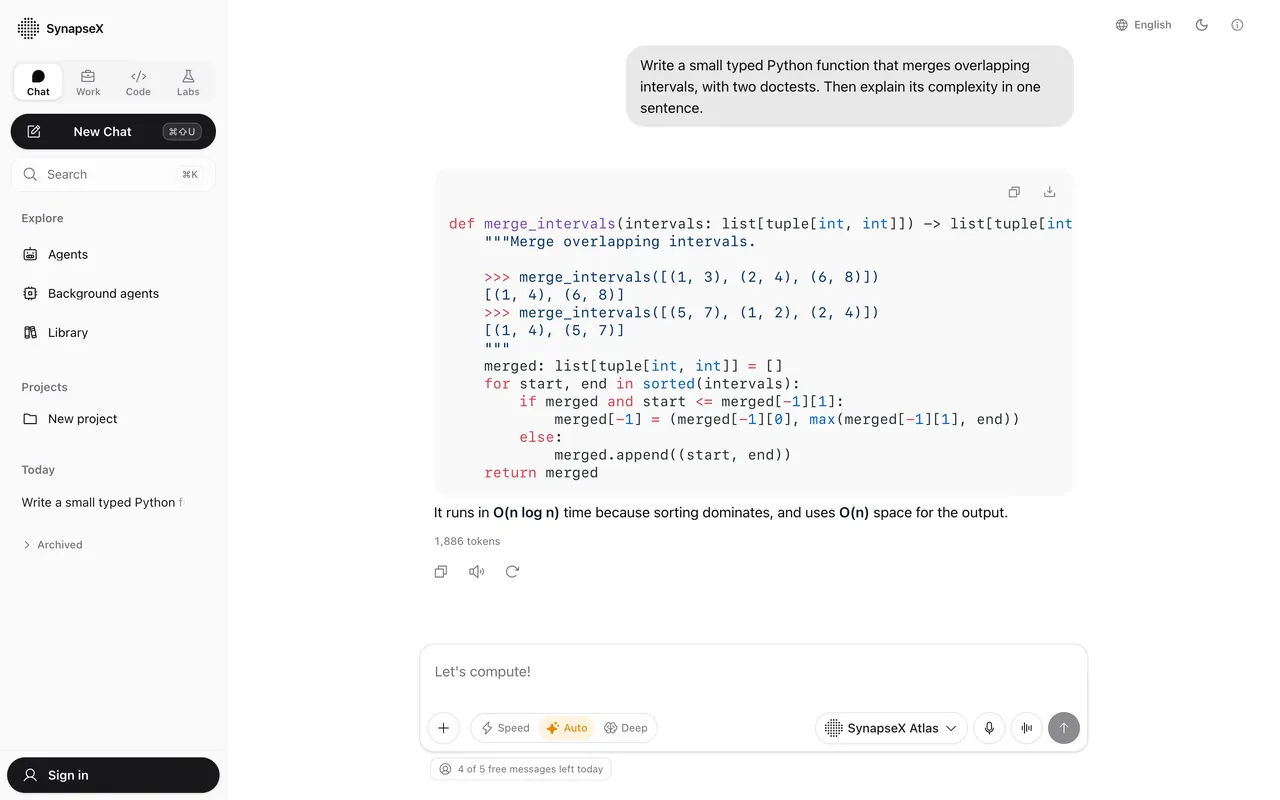
Write code with its tests
A typed Python function with doctests and its complexity in one sentence.
A training programme with a written gate.
We do not pre-train from zero. We start from an openly licensed base model, and a model we release names its base and that licence.
Code, science and quantum examples, with licences checked source by source and overlap audited. We do not train on your private research without an explicit, revocable opt-in.
Post-training runs on LUMI-G under EuroHPC allocation EHPC-AIF-2025LS13-019, with GPU-hours budgeted for each stage before it starts.
The same fixed question set goes to the base and to the candidate, and the rule is written before the run. A candidate that loses is recorded as a loss.
A candidate joins the catalogue only if it passes. Until then it stays out, whatever it cost to train.
Where it stands
The programme and the catalogue are separate things. Models from this programme join the catalogue only after they pass the gate. None has so far.
Your data
We do not train our models on your private research without an explicit, revocable opt-in. The full data-use policy is in the privacy policy.